You are generating images on an RTX 5080 and you would like to throw a second job at another card in the background. If you use ComfyUI daily, that situation comes up. The machine here has an RTX 5080 (16GB) in the main PC and a second card attached over Oculink through a MINISFORUM DEG1 eGPU dock. Measurements are split by date: the April 2026 numbers are 5080 + RTX 4070 Super, the September 2026 re-measurements are 5080 + RTX 5060 Ti 16GB, and every table says which. Running ComfyUI on two GPUs has an unusually wide gap between what works and what does not. This article separates what was measured here from what is only documented, and sets out which parts are practical.
- Port separation ― two ComfyUI instances on different ports, one per GPU ― is the most practical dual-GPU setup. Two images finish in roughly the time the slower card needs for one
- Stock ComfyUI cannot present 16GB + 12GB as one transparent 28GB pool. Splitting a model’s layers across cards is a separate matter and is possible with custom nodes
- Some LLM tools such as Ollama can pseudo-pool VRAM through a layer split across GPUs. Whether that helps depends on what you are running
The original measurements (2026-04-10) used an RTX 5080 as the main card and an RTX 4070 Super 12GB over Oculink. In September 2026 the sub-GPU was replaced with an RTX 5060 Ti 16GB and the same questions were measured again; those results are in the later sections. The old tables cannot be used as a performance comparison against the new ones, so each table states its measurement date and configuration. The RTX 4070 Super in the title refers to the original setup.
- Port separation ― the most practical dual-GPU setup
- Startup settings
- Choosing which GPU to use ― CUDA_VISIBLE_DEVICES and --cuda-device
- April 2026: the first measurement, and what it cannot show
- September 2026: re-measured with an RTX 5060 Ti, this time with a control
- With the startup options matched, how far apart are the two cards?
- The same settings move a few percent between runs — what this measurement can and cannot resolve
- Raising the load ― speed goes slightly the other way, VRAM drops by 3GB
- What happens with video ― both cards sit against the ceiling at once
- Simultaneous processing through multi-GPU nodes ― the advanced option
- VRAM does not simply add up ― the biggest dual-GPU misconception
- The exception: Ollama can pseudo-pool VRAM
- Where dual GPU fits, and where it does not
- Power and PSU considerations
- Troubleshooting FAQ
- Q1: “No CUDA device available” when ComfyUI starts
- Q2: One GPU is far slower than the other
- Q3: The browser tab for the sub-GPU does not respond
- Q4: How do I pin Ollama to one specific GPU?
- Q5: The main GPU drops out during parallel work while the sub-GPU keeps going
- Q6: For a new build in 2026, RTX 5060 Ti 16GB or RTX 4070 Super as the sub-GPU?
- Q7: Is there a noticeable difference between Oculink x4 and PCIe x16 during generation?
- Summary
- References
Port separation ― the most practical dual-GPU setup
If you want to use ComfyUI with two GPUs, port separation is the first thing to try. It is simple: launch one ComfyUI instance per GPU and give each its own port. Main GPU on 8188, sub-GPU on 8189. Open two browser tabs and you have two independent generation environments.
Startup settings
The launcher used here for the main GPU (RTX 5080) is --port 8188 --cuda-device 0 --reserve-vram 1.5 --bf16-unet --bf16-text-enc. For the sub-GPU it is --port 8189 --cuda-device <the ID of that card> --fp8_e4m3fn-unet --fp8_e4m3fn-text-enc. You do not need to set CUDA_VISIBLE_DEVICES on either side.
Do not copy the device IDs literally. Which physical card ID 0 lands on depends on enumeration order, so pin the order with set CUDA_DEVICE_ORDER=PCI_BUS_ID before launching, check with nvidia-smi which card is which, and write those numbers in.
| Item | Main GPU (RTX 5080) | Sub-GPU (Oculink; RTX 5060 Ti at the time of writing) |
|---|---|---|
| Environment variables | set CUDA_DEVICE_ORDER=PCI_BUS_ID | set CUDA_DEVICE_ORDER=PCI_BUS_ID |
| Port | --port 8188 |
--port 8189 |
--cuda-device |
0 | the ID of that card in your enumeration |
| VRAM mode | not set (ComfyUI’s default dynamic management) | not set (ComfyUI’s default dynamic management) |
| Reserved VRAM | --reserve-vram 1.5 |
not set |
| dtype options | --bf16-unet --bf16-text-enc |
--fp8_e4m3fn-unet --fp8_e4m3fn-text-enc |
The argument definitions live in comfy/cli_args.py in the ComfyUI official repository. Note that the two sides are not running the same settings: ComfyUI defines --bf16-unet as running the diffusion model in BF16, while --fp8_e4m3fn-unet stores the UNet weights in FP8. These are not a matched pair, and the sub-GPU here also has no reserved VRAM. That means the two columns of seconds below cannot be read as a comparison of the two cards. Bfloat16 Tensor Core support on Ampere and later is documented in the NVIDIA Ampere GPU Architecture Tuning Guide (“Improved Tensor Core Operations”).
--reserve-vram is not a hard ceiling. In a separate test of ComfyUI startup flags on this machine, a run that asked for 13GB still peaked above the figure that number implies. It works as “raise it and the peak tends to come down”, not “the peak stops here”; the 1.5 above is a starting point that leaves room for desktop rendering and other resident processes. Both instances leave the VRAM mode unset, i.e. ComfyUI’s default dynamic management.
nvidia-smi which card holds which ID, and pass that ID to --cuda-device. The quickest confirmation is to start one generation and watch which GPU’s utilisation moves.Choosing which GPU to use ― CUDA_VISIBLE_DEVICES and --cuda-device
The CUDA_VISIBLE_DEVICES environment variable filters which GPUs are “visible” to the CUDA runtime. With current ComfyUI, however, you rarely need to set it yourself: --cuda-device already does that job. It rewrites CUDA_VISIBLE_DEVICES internally, keeping only the ID you pass, and it overrides the variable even if you set it beforehand (checked on v0.31.1 here; v0.34.0, released 2026-08-26, behaves the same). So --cuda-device 1 is enough to give that process a single visible card. What actually trips people up is which physical card that ID lands on, because it depends on enumeration order.
To control that order, use the CUDA_DEVICE_ORDER environment variable. The default is FASTEST_FIRST (performance order), so on a dual-GPU machine the numbering can swap in ways you did not expect. Set CUDA_DEVICE_ORDER=PCI_BUS_ID to enumerate by ascending PCI bus ID instead. This behaviour is documented in the NVIDIA CUDA Programming Guide, “CUDA Environment Variables”, which lists FASTEST_FIRST as the default and PCI_BUS_ID as enumeration by ascending PCI bus ID.
The advantage of this method is that it keeps the generation workload off the main GPU, so a job on the sub-GPU does not compete for the card you are working on, and a speed difference between the two does not get in the way. The trade-off is that system RAM usage increases, since you are running two instances. The 96GB machine here has not run into a wall, but we have not measured where that wall is — it moves with the models, custom nodes and caches you load, so whether the RAM in your own build (32GB, say) is enough depends on what you load.
April 2026: the first measurement, and what it cannot show
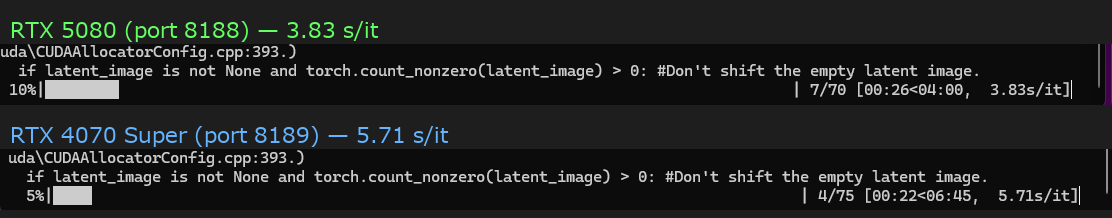
The table below is from the original setup, with generation jobs submitted to both GPUs at the same time on this test bench (i7-14700F / 96GB RAM).
| GPU | Connection | Sampling speed | Steps |
|---|---|---|---|
| RTX 5080 (16GB) | PCIe x16 | 3.83 s/it | 70 steps |
| RTX 4070 Super (12GB) | Oculink (PCIe x4) | 5.71 s/it | 75 steps |
Measured 2026-04-10 with the RTX 4070 Super as sub-GPU. This is a different workload from the September table further down (SDXL, 1280×720, 30 steps), so numbers cannot be carried between the two.
Two things have to be said before you read anything into this table. First, the two rows are not the same workload — 70 steps against 75, and the per-step figures (s/it) are not the time to finish one image. You cannot line the two numbers up as a comparison of the cards, and they are not a basis for any ratio between them. Second, this run recorded no solo control: both cards were measured while running together, so “they did not slow each other down” is not something these numbers can show. What they do show is that the Oculink card kept working at a usable pace while the main card was busy. The September re-measurement below adds the control that was missing here.
September 2026: re-measured with an RTX 5060 Ti, this time with a control
The sub-GPU was replaced with an RTX 5060 Ti 16GB, so the same question was measured again: do two cards slow each other down when both are working? This time the same workflow, resolution and step count went to both sides, and each card was also measured on its own as a control — which the April run did not have.
| Condition | Main: RTX 5080 PCIe x16, bf16 |
Sub: RTX 5060 Ti Oculink x4, fp8 |
|---|---|---|
| Alone (median of 5) | 6.55 s | 11.48 s |
| Both at once (median of 5) | 6.50 s | 11.46 s |
| Difference | −0.8% | −0.2% |
| Spread when alone (min–max) | 6.39–6.64 s | 11.39–11.53 s |
| Per step | 0.218 s | 0.383 s |
SDXL, 1280×720, 30 steps. Two ComfyUI instances (8188 = GPU0, 8189 = GPU1), one warm-up discarded per side, then 5 runs each, completion detected by polling every 0.25 s. Measured 2026-09-03. Note that this particular run attached to ComfyUI instances that were already up, so the startup flags could not be confirmed at run time — the later runs were launched fresh.
Neither card showed a clear slowdown from running in parallel. This run came out slightly negative (marginally faster together), which is worth holding lightly — the runs launched from a cold start later all landed a few percent on the slow side instead. Either way the differences sit inside the spread of the solo runs (6.39–6.64 s on the main card), so what this supports is “no slowdown of a size this measurement can detect”, not “no slowdown”.
The useful number is the wall clock. Two images finish in 11.57 s together, against 6.55 + 11.48 = 18.03 s if you ran them one after the other. Two images come out in roughly the time the slower card needs for one. That is what port separation actually buys you: not a faster single image, but two images for the price of the slower one.
--bf16-unet / --bf16-text-enc with reserved VRAM, the sub-GPU uses --fp8_e4m3fn-unet / --fp8_e4m3fn-text-enc with none. What this table supports is the difference between “alone” and “together” on the same side. A matched-condition comparison follows.With the startup options matched, how far apart are the two cards?
The measurement above ran the two cards on the settings they are used with day to day. To compare the cards themselves, the sub-GPU was relaunched with the main card’s settings — same precision (--bf16-unet / --bf16-text-enc), same --reserve-vram 1.5, same disabled preview — leaving only the port, the device ID and the output directory different. What remains is the cards and how they are attached (PCIe x16 against Oculink x4).
| Condition | RTX 5080 PCIe x16 |
RTX 5060 Ti Oculink x4 |
|---|---|---|
| Alone (median of 5) | 6.79 s | 11.42 s |
| Per step | 0.226 s | 0.381 s |
| Spread when alone | 6.22–6.92 s | 11.40–11.53 s |
| Both at once (median of 5) | 6.96 s | 11.49 s |
SDXL, 1280×720, 30 steps, one warm-up discarded per side then 5 runs, 0.25 s polling. Measured 2026-09-04.
Matched like this, the gap on this machine is about 1.68x (the ratio itself moves between runs; across four runs it spread over 1.68–1.79x, discussed below). That is not “the performance difference between an RTX 5080 and an RTX 5060 Ti” — it is the difference between these two cards, on these connections, with this workflow. The sub-GPU hangs off Oculink x4, and no measurement here swapped the same card between x16 and x4, so the contribution of the link cannot be separated out. Image generation keeps its main work inside the GPU once the model is loaded, so if the link width matters anywhere it is likely in loading and model swapping.
Running in parallel moved the main card by +2.5% and the sub by +0.6%. The solo runs themselves spread 6.22–6.92 s, which is wider than that difference. Repeating the measurement under other conditions, every run that was launched from a cold start came out on the same side, +2.2% to +2.6% on the main card. The direction is consistent, but the spread of the solo runs is larger, so the precision of that figure is not something to claim — the honest statement is “in these three runs it was +2.2% to +2.6%”.
For the wall clock: 6.96 s and 11.49 s together finish in 11.61 s (median), against 6.79 + 11.42 = 18.21 s run sequentially. About 1.57x, essentially the same as the day before. Matched settings or not, what port separation gives you is the same: two images in the time the slower card takes for one.
The same settings move a few percent between runs — what this measurement can and cannot resolve
Before taking any of these numbers at face value, it is worth pinning down how much the measurement itself wanders. The same workflow was run four times, changing only the sub-GPU’s settings. The main RTX 5080 had identical settings in all four, so it serves as the yardstick. The fourth run used bf16 with no reserved VRAM — identical to the fp8 launcher except for the two dtype flags — so that the presence of reserved VRAM is itself controlled.
| Run | Sub dtype | Sub reserved VRAM | RTX 5080 alone same settings all four |
RTX 5060 Ti alone | Parallel delta 5080 / 5060 Ti |
Sub-GPU VRAM resident → peak |
|---|---|---|---|---|---|---|
| 2026-09-03 ※ | fp8 | none | 6.55 s | 11.48 s | −0.8% / −0.2% | 3,600 → 6,032 MiB |
| 2026-09-04 ① | bf16 | 1.5 | 6.79 s | 11.42 s | +2.5% / +0.6% | 6,820 → 9,252 MiB |
| 2026-09-04 ② | fp8 | none | 6.56 s | 11.70 s | +2.6% / +0.1% | 3,588 → 6,020 MiB |
| 2026-09-04 ③ | bf16 | none | 6.39 s | 11.46 s | +2.2% / +0.2% | 6,820 → 9,252 MiB |
※ The 2026-09-03 run attached to ComfyUI instances that were already running, so its startup flags could not be verified at run time. The three runs on 2026-09-04 were each launched fresh and confirmed.
The yardstick differs depending on what you are looking at. The main card moved 6.39–6.79 s (6.3%) between runs on identical settings, and within a single run of five it spread 3.7–11.3%. The sub-GPU, by contrast, stayed within 1.1–1.5% inside a run, and between runs two fp8 runs came out at 11.48 s and 11.70 s (1.9%). Do not use the main card’s wander as the yardstick for a question about the sub-GPU’s settings — they are different axes.
On the parallel delta, the three runs whose startup was confirmed all agreed: +2.2% to +2.6% on the main card, +0.1% to +0.6% on the sub. The direction is consistent. But the spread of five solo runs is larger than that, so the precision of a figure in the low single digits is not something to claim. What can be said is “in these three runs it was +2.2% to +2.6%” — not that it will never fall further, and not that it never falls at all. The one negative result, where parallel looked faster, came from the run that attached to instances that were already up.
What about the sub-GPU’s dtype? Two fp8 runs came out at 11.48 s and 11.70 s; the bf16 runs are just below at 11.42 s and 11.46 s. With the same fp8 setting varying by 1.9% between runs, that ordering cannot be given any weight at this load. Whether one is faster than the other is not readable from this table — the same difference survives at a heavier load, where it can be resolved, and that is covered further down.
The VRAM figures, on the other hand, repeated well past the noise. Measuring bf16 both with and without --reserve-vram 1.5 gave 6,820 MiB resident and 9,252 MiB peak in both cases — not a single MiB apart. Reserved VRAM plays no part in this difference. What remains is the dtype: fp8 sits at 3,588 / 3,600 MiB resident, about 3,232 MiB lower. And the amount added during generation was exactly 2,432 MiB in all four runs. The difference shows up only in what is resident for the model; what the generation itself consumes does not move — which fits the description of a weight storage format.
Finally, throughput for the two cards together stayed within 1.53–1.57x across all four runs. The value of port separation is not that nothing slows down; it is that multiplier.
Raising the load ― speed goes slightly the other way, VRAM drops by 3GB
Everything so far ran SDXL at 1280×720, where bf16 peaks at 9,252 MiB. Against the 16,311 MiB the card actually offers, that is 57%. There was simply too much headroom for fp8 to buy anything. So the load was raised.
But not past the point where it stops fitting. The moment something spills, what you are measuring turns into how the overflow is handled, and the dtype itself disappears behind it. The target is a load where bf16 sits close to the ceiling but still fits, and fp8 brings the same work comfortably back down. Same model, same step count, same sampler, same seed; only the resolution changed, to 2048×1408 (3.13x the pixels). What differs is the dtype flags and the pixel count.
| SDXL 2048×1408, 30 steps RTX 5060 Ti 16GB (Oculink x4), alone |
bf16 | fp8 |
|---|---|---|
| Time (median of 5 warm runs, two separate runs) | 36.19 / 36.32 s | 36.52 / 36.56 s |
| Range across all 10 runs | 36.15–36.38 s | 36.49–36.61 s |
| Resident when the model is loaded | 6,820 MiB | 3,588 MiB |
| Peak across the GPU | 14,372 MiB | 11,140 MiB |
| Added during generation | 7,552 MiB | 7,552 MiB |
| Share of the card | 88% | 68% |
| Startup options | --bf16-unet / --bf16-text-enc |
--fp8_e4m3fn-unet / --fp8_e4m3fn-text-enc |
The two launchers are identical apart from the two dtype flags, and neither carries --reserve-vram. ComfyUI was relaunched for each, then one warm-up discarded and 5 runs taken, twice per dtype. Completion detected by polling every 0.25 s.
fp8 came out slower in both runs. Pairing them up: 36.19 s against 36.52 s (+0.91%), and 36.32 s against 36.56 s (+0.66%). Pooling all ten runs, bf16 spans 36.15–36.38 s and fp8 spans 36.49–36.61 s, so the ranges do not overlap at all. The size of the difference, though, is only good to about “under 1%” with this method. Completion is checked every 0.25 s, which against 36 s is 0.69% of coarseness — the same order as the difference being looked at. “It lands on the slower side” reproduced in both runs; do not take “how much slower” as a precise figure.
That is the opposite of the intuition that fp8, being lighter, should be faster. It is not unreasonable mechanically, though. --fp8_e4m3fn-unet specifies how the weights are stored, not the form the arithmetic takes. Converting to a compute format at run time, or additional handling around it, is a candidate for where the difference comes from (ComfyUI does have an fp8 compute path, and which path is taken varies with conditions). This measurement only looked at elapsed time, so the cause is not established. Running the matrix multiply itself in fp8 is a separate opt-in, --fast fp8_matrix_mult, which was not enabled. In this RTX 5060 Ti / SDXL configuration, both runs put fp8 under 1% on the slow side — that is as far as it goes, and it is not a claim that fp8 costs 1% in general.
Seeing that 1% at all requires fine-grained completion detection. Checking every 2 seconds collapses bf16 and fp8 onto the same value and reads as “no difference” — which is exactly what happened here on the first attempt. What is being measured is not the elapsed time itself but the round-up to the next check, so the checking interval is the resolution. It is 0.25 s here.
The VRAM side, by contrast, reproduced far beyond the noise. Resident memory sits at 6,820 MiB against 3,588 MiB, a gap of 3,232 MiB. Yet the amount added during generation is 7,552 MiB in both cases, identical. The 3,232 MiB gap in the peak is that resident gap, unchanged from start to finish. The lighter load showed the same shape: at 1280×720 the added amount was 2,432 MiB for both, with the same 3,232 MiB resident gap. Tripling the pixels tripled the added amount and left the gap alone. Across these two resolutions, the dtype moves only what is resident for the model; it does not touch what the generation itself consumes. That fits the description of a storage format.
In this test, fp8 bought headroom, not speed. Even at a load using 88% of the card, dropping to fp8 does not make it faster. Where it starts to matter is when something does not fit at all — and from there you are into swapping parts in and out, or pushing them to the CPU, which is where the real subject of this article begins.
This was one model on one card. Change the model and the weight-to-activation ratio changes with it. The fp8 matrix multiply (--fast fp8_matrix_mult) was not enabled.
What happens with video ― both cards sit against the ceiling at once
Everything above was image generation. Video changes the premise. Producing 41 frames at 512×320 with LTX-2 19B (Q4 quantised) peaks at 15,181 MiB on the RTX 5080 and 14,820 MiB on the RTX 5060 Ti — 93% and 91% of each card. One card is close to full before anything else happens. The image section pushed bf16 to 88% deliberately; with video that is the starting point.
| LTX-2 19B Q4, 512×320, 41 frames | RTX 5080 PCIe x16 |
RTX 5060 Ti Oculink x4 |
|---|---|---|
| Alone (median, two runs) | 33.63 / 33.90 s | 52.21 / 52.18 s |
| Both at once | 32.07 / 32.34 s | 51.29 / 51.01 s |
| Peak across the GPU | 15,181 / 15,316 MiB | 14,820 MiB |
| Share of the card | 93–94% | 91% |
| First run (model load included) | 113.09 / 97.23 s | 120.04 / 118.47 s |
One warm-up discarded per side, then 3 runs each, 0.25 s polling. ComfyUI was relaunched for both runs. The two sides use different startup options (main bf16, sub fp8), so their seconds cannot be read as a comparison of the cards.
Two videos finished in 51.41 s and 51.12 s. Run sequentially they would take 85.84 s and 86.08 s, so the ratio is 1.67x and 1.68x — better than the image case (1.53–1.57x). And it is shorter than the slower card needs on its own (52.21 s). With both cards using around 90% of their VRAM.
Per-card time did not get worse in parallel either. If anything both runs came out slightly faster, at −4.6% on the main card and −1.8% and −2.2% on the sub. That cannot be read as a benefit of running in parallel. The three parallel runs break down as 33.57, 32.05, 32.07 and 33.62, 31.95, 32.34 — only the first one matches the solo figure. If parallelism itself were responsible the first run would already be fast, and this shape does not explain that. A first run including the model load takes 97.23–120.04 s here, 2.27–3.36x the warm figure, so one discarded warm-up may well not be enough. What can be said is “running two at once does not make it worse”, not “it makes it better”.
The seconds above still have the two sides on different startup options. So both were set to the same configuration and measured again with only one ComfyUI running. That gives RTX 5080 at 34.79 s and RTX 5060 Ti at 50.28 s, a gap of 1.45x — smaller than the 1.55x you get from lining up the unmatched runs. Across these two measurements the apparent ratio moved from 1.55x to 1.45x, which is the sort of difference an unmatched comparison can carry. The two are separate runs, though, so not all of it can be pinned on the startup options (the same RTX 5080 moved 3.6% across three solo runs). VRAM came out lower matched as well, at 13,924–14,020 MiB.
While at it, the effect of the other ComfyUI sitting idle was measured too. Running the RTX 5080 from the same launcher gives 34.79 s with only one instance up, against 33.63 s and 33.90 s with a second one idle. The three single-instance runs spread 34.30–35.55 s (3.6%), and that difference sits inside it. Whatever the idle instance costs is not visible at this resolution.
Where video really starts to matter is past this point. If one card is 91% full at this size, raising the resolution or the frame count stops it fitting. From there it is what was described earlier: split one generation across two cards, or move layers onto the other card. What port separation earns you is the throughput of running two jobs side by side; it does nothing for a single job that will not fit.
The dtype comparison does not carry over to video here. LTX-2’s body is a Q4 GGUF, so a startup flag does not replace that stored format. That is not the same as saying the flags are irrelevant — the GGUF loader still goes through ComfyUI’s own model loading, and the dtype decision there returns --bf16-unet or --fp8_e4m3fn-unet first if either is set (checked on v0.31.1 here). Since GGUF dequantises at inference time, the startup setting cannot be assumed to have no effect on the execution path. So these two conditions are used neither as a comparison of the cards nor of the dtypes.
One more note on method. The first attempt polled for completion every 2 seconds, which rounded times into 2-second steps and produced a reading where the main card looked 20% faster in parallel — a swing the solo spread (6.39–6.64 s) cannot explain. What was actually being measured was the round-up to the next check. The interval is the resolution, so it was dropped to 0.25 s and everything above was measured again.
Simultaneous processing through multi-GPU nodes ― the advanced option
Port separation runs two independent environments. There are also custom nodes that make one workflow use two GPUs. Three are worth knowing about.
| Node | How it works | Speed | VRAM efficiency | Mismatched GPUs |
|---|---|---|---|---|
| ComfyUI-MultiGPU | Assigns UNet / CLIP / VAE to different devices (sequential execution) | × | ○ saves memory | △ little affected |
| ComfyUI-Distributed | Runs different seeds in parallel; for upscaling, distributes tiles | ○ higher throughput (upscaling also shortens a single image) | × full copy on each GPU | △ works; a large gap becomes the bottleneck (load_balance available) |
| ComfyUI-ParallelAnything | Splits a batch across GPUs | ○ shortens the whole batch | × full copy on each GPU | △ mixed speeds work; the faster card waits at each step, but a percentage split compensates |
ComfyUI-MultiGPU lets you choose which device each model component ― UNet, CLIP, VAE ― is loaded onto. Alongside the stock loaders it provides ControlNet, CLIP Vision and GGUF variants. Execution is sequential, so the character of it is that you no longer need to fit everything on one card, which frees up VRAM. The official repository describes it as being for freeing VRAM on the compute card and for running models that do not fit, and lists .safetensors and GGUF quantised models broadly, including FLUX, SDXL, SD1.5, LTX Video and WanVideo 2.2. The more you move off, though, the more transfers you insert; it is a technique for fitting things, not for making them faster. Nothing here was measured on this machine — that description follows the official repository.
ComfyUI-Distributed takes a different approach, running the same workflow on several GPUs at once. Different seeds generate simultaneously, so throughput goes up. In that mode the time for a single image does not change; you get more images per unit time. Upscaling is the exception: it can distribute the tiles of an Ultimate SD Upscale across workers, and the project states that this speeds up a single upscale as you add GPUs (ComfyUI-Distributed official repository, as of 2026-09-04). That works because tiles are separable; the generation itself is not being split.
ComfyUI-ParallelAnything splits a batch across GPUs. Each GPU needs a full copy of the model, so VRAM use doubles. The project notes that mixing GPU architectures works but the faster card waits for the slower one at each step, and supports compensating with a percentage split.
Port separation is used here for a reason. There is a real speed gap between the RTX 5080 and the sub-GPU (RTX 4070 Super in April, RTX 5060 Ti now), and with the simultaneous-processing nodes the slower card becomes the bottleneck. Note that the 3.83 / 5.71 s/it figures from April were taken without matching resolution or step count, so they cannot be used as the basis for a ratio; the matched re-measurement is above, and it put the current pair at about 1.68x. When the cards differ noticeably in speed, running them independently is the sensible choice.
VRAM does not simply add up ― the biggest dual-GPU misconception
“Can I combine the 16GB on the RTX 5080 with the 12GB on the sub-GPU and use 28GB?” This is probably the most common misunderstanding when people consider a second card. The answer is that you cannot present 16GB and 12GB to ComfyUI as one transparent 28GB pool. Each card’s VRAM is physically separate, and stock ComfyUI has no mechanism to treat several GPUs as a single transparent pool. Splitting a model’s layers across cards is a different matter, and the custom nodes above can do it.
NVLink / SLI / NVSwitch, sorted out
NVLink is a high-bandwidth interconnect between GPUs, and the RTX 3090 and RTX 3090 Ti were the last GeForce cards to support it (the official specification table lists NVLink as Yes for both). The RTX 40 series and later do not: the official RTX 4090 specification table lists “NVIDIA NVLink (SLI-Ready)” as No. Data center parts have NVSwitch, an interconnect that does not reach consumer cards. But NVSwitch itself is about bandwidth and latency; it is not a mechanism that turns several VRAM pools into one large pool. The part that lets software address memory as a single space is a CUDA feature, which sits at a different layer from the interconnect.
NVIDIA describes NVLink as a high-bandwidth interconnect between GPUs and NVLink Switch as the fabric that connects them all-to-all (NVIDIA NVLink page). On current NVIDIA products both belong to the data-center stack, and what they are about is bandwidth and latency.
You will also see “share VRAM with SLI” mentioned. SLI is a frame-splitting technique for games and has nothing to do with pooling VRAM.
An attempt was made on this machine to nominate the sub-GPU as an offload target for the RTX 5080’s VRAM, and ComfyUI’s design does not allow it. Two cards’ VRAM cannot be used as one transparent region. Placing a model or its layers across them is a separate route and does exist ― ComfyUI-MultiGPU, described above ― and it does let you run something that will not fit on one card. It is placement, not a larger pool, and it does not make a single generation faster (if it moves work off the CPU back onto a GPU, the result can still end up quicker). If the UNet alone will not fit, a single card with enough VRAM is the straightforward answer.
The exception: Ollama can pseudo-pool VRAM
ComfyUI cannot pool VRAM, but LLM inference is a different story. Ollama can spread a transformer’s layers across several GPUs using a layer split (what llama.cpp calls --split-mode layer; distinct from tensor parallelism, where several GPUs share one layer). Data flows through the layers in order, and the practical result is that a model too large for one card can be loaded across two. It is not the case that 16GB + 12GB is all available for weights ― the KV cache and working buffers come out of the same VRAM.
The advantage of this layer split is that inter-GPU traffic stays low. Each GPU holds a contiguous slice of layers and the KV cache for those layers, and processes its own range in turn; what crosses between GPUs during inference is mainly the intermediate result at a layer boundary. Compared with tensor parallelism, that keeps the transfer volume down (llama.cpp official docs/multi-gpu.md; Ollama builds on this implementation). The same document notes that the layer mode tolerates slow interconnects, which is the general basis for it working over a narrow link. Whether that holds specifically over Oculink (PCIe x4) is not something the official documentation addresses — that part comes from measurements on this machine, written up separately in the Oculink GPU setup article. The Ollama GPU documentation itself only covers which GPUs to expose, not how a model gets distributed.
Measured on this machine with two GPUs
| Model | RTX 5080 alone | Dual GPU (5080 + 4070 Super) | Difference |
|---|---|---|---|
| Qwen3 8B | 99.15 tok/s | 130.68 tok/s | +32% |
| Gemma3 12B | 85.90 tok/s | 84.47 tok/s | about the same |
| Qwen3 32B | 5.69 tok/s (spilling to CPU) | 11.24 tok/s | +97% |
Measured on the April configuration (i7-14700F / 96GB RAM). The model tags, quantisation and Ollama version were not recorded for this run, so it cannot be placed alongside the September measurements above.
Qwen3 8B fits on a single GPU to begin with, and it still gained 32%. What produced that is not established here — whether the layers were actually distributed across both cards was not confirmed with ollama ps, so the cause cannot be pinned down from this measurement. Gemma3 12B, meanwhile, barely moved. For models that fit on one card, a second card does not produce a consistent result.
The dramatic case is Qwen3 32B. On the RTX 5080 alone the model exceeds 16GB, part of it spills to the CPU, and throughput collapses to 5.69 tok/s. Split across two cards it runs at 11.24 tok/s. The gain here is not really about two GPUs; it is about not falling back to the CPU. That is the situation where a second card earns its place for LLM work.
Where dual GPU fits, and where it does not
Good fits
Running two different generation jobs at once. Iterating on a prompt on the main GPU while the sub-GPU grinds through a batch, or keeping image generation running while you work. In the measurements here neither side showed interference that this method could detect, and the speed gap was not a problem.
Large models in LLM inference such as Ollama. Being able to run a model that does not fit on one card without CPU offload is a real benefit, as the Qwen3 32B figures show.
Two cards of the same speed, when you want volume. With matched GPUs, ComfyUI-Distributed or ParallelAnything gives you batch parallelism: the same time per image, more images per unit time. Each GPU still needs a full copy of the model, so two cards do not increase the size of model you can run, and it is not a VRAM saving. This machine has two cards of different speeds, so that “two matched cards” condition was never measured here.
Poor fits
Wanting one image to generate faster. None of the three custom nodes above splits a single denoising step across GPUs. Other approaches do exist ― the stock MultiGPU CFG Split, and Raylight ― but they cannot be combined with port separation. As noted earlier, upscaling is the exception: ComfyUI-Distributed can distribute tiles and shorten a single image. What is being discussed here is generation itself.
Wanting to pool VRAM for one model. ComfyUI has no transparent VRAM pooling across GPUs. You can still lower what one card has to hold ― ComfyUI-MultiGPU places UNet, CLIP and VAE on separate devices ― but that is placement, not a bigger pool, and it does not speed up a single generation. If the UNet alone will not fit, a single larger card is the straightforward answer.
Two cards of very different speeds, running simultaneously without tuning the split. With ComfyUI-Distributed or ParallelAnything generating on both at once, the slower card sets the pace unless you intervene. Both have ways to adjust ― load_balance on the former, a percentage split on the latter ― so this is the untuned case. ComfyUI-MultiGPU runs sequentially and does not have this problem. For something like an RTX 5080 paired with an RTX 4070 Super, running them independently is the more efficient arrangement overall.
Power and PSU considerations
Before adding a second card, the physical constraints ― power and slots ― are what usually bite first. Even with two x16 slots on the board, the second is often wired to fewer lanes through the chipset, and a triple-fan card tends to block the neighbouring slot physically. Moving the second GPU outside the case over Oculink to an eGPU dock, which is the arrangement used here, avoids that.
Power is the part most often overlooked. The RTX 5080’s TGP is 360W; the sub-GPU is 220W for the April RTX 4070 Super and 180W for the current RTX 5060 Ti. The i7-14700F is specified up to 219W. Adding the rated figures gives 799W for the 4070 Super configuration and 759W for the 5060 Ti. That is a sum of specification maxima, not a measurement — it does not mean all three hit those numbers at the same moment, and total system draw was not measured here.
| Component | Rated power | Source |
|---|---|---|
| RTX 5080 | 360W (TGP) | NVIDIA official specs |
| RTX 4070 Super | 220W (TGP) | NVIDIA official specs |
| RTX 5060 Ti 16GB | 180W (TGP) | NVIDIA official specs |
| i7-14700F | 219W (Max Turbo Power) | Intel official specs |
Here the sub-GPU on Oculink runs from its own PSU. The eGPU dock requires a dedicated ATX supply, so the main PSU does not have to carry the sub-GPU’s draw directly — that is the benefit of this arrangement. What it separates is the load downstream of each PSU, not the AC side of the wall socket or the thermal environment around the case. A dual-PSU build costs you wiring complexity, but it does give each supply more thermal headroom on long generation runs. If you build on a single PSU, a 1000W-class unit for both GPUs plus CPU is the usual target, with 80PLUS Gold or better for efficiency and heat.
The dock here is paired with a 750W supply. For a sub-GPU in the RTX 4070 Super class, 600–750W leaves plenty of margin and there is no need to over-specify. It is also worth dropping the assumption that the dock is only for a small second card: if reworking the existing PC is not practical, putting a high-TGP card such as an RTX 5090 on the dock side adds it over Oculink without touching the main PSU or the case. The capacity requirement simply moves to the dock’s own supply, so the 600–750W figure above only applies to a 4070 Super-class card. If the second card is only needed for heavy work, you can leave the dock unpowered on ordinary days and boot with it enabled when you need it, which avoids carrying a high-end card’s idle draw the rest of the time; idle figures vary quite widely by driver and display configuration, so treat it as tens of watts rather than a fixed number. Note that OCuLink is not hot-pluggable. The dock’s manual asks you to power the host down before connecting or disconnecting the cable — pulling it live, or forcing the dock off mid-session, risks damaging the ports. Switch it in and out before boot or after shutdown, not during a session.
Troubleshooting FAQ
Q1: “No CUDA device available” when ComfyUI starts
The likeliest cause is that --cuda-device was given an ID that does not exist on the machine. You do not need to line up an environment variable with it: current ComfyUI treats --cuda-device as both “use this device” and “hide the others”. With two cards the ID is 0 or 1, and which physical card that is depends on enumeration order — set CUDA_DEVICE_ORDER=PCI_BUS_ID first and check against nvidia-smi. Older guides pair it with CUDA_VISIBLE_DEVICES; setting both today just means --cuda-device overwrites the variable.
Q2: One GPU is far slower than the other
Separate two things first: is the per-step time (s/it) slow, or is the total time to finish an image long? For s/it, look at the card’s own performance, at whether VRAM is overflowing and work is spilling to the CPU, and at power and thermal limits. Those dominate, because once the model is loaded the sampling loop stays inside the GPU. PCIe width comes into it when the total is long — model loading and swapping cross the bus, and Oculink over M.2 is usually PCIe x4, so loads take longer than on an x16 card. Note that this article never compared the same card at x16 and at x4, so the size of that effect is not something it can attribute.
Q3: The browser tab for the sub-GPU does not respond
Either --port 8189 was not passed, or Windows Firewall is blocking it. Check the listening state with netstat -ano | findstr 8189. If the sub-GPU’s console shows “To see the GUI go to: http://127.0.0.1:8189”, it is listening correctly.
Q4: How do I pin Ollama to one specific GPU?
Use the CUDA_VISIBLE_DEVICES environment variable to limit what Ollama can see (for example, set CUDA_VISIBLE_DEVICES=0 uses only GPU 0). Set it before starting the Ollama server, or add it to override.conf if you run it under systemd. This is the opposite of the ComfyUI case above: ComfyUI has --cuda-device, which overrides the variable, so you do not need to set it there — for Ollama the environment variable is what the official documentation points you to. Note that num_gpu controls how many layers are offloaded to the GPU, not which GPU is used, so treat it as separate from pinning. It is also a request/Modelfile parameter rather than a server environment variable: OLLAMA_NUM_GPU does not appear in the environment list that current ollama serve --help prints. You can check placement with ollama ps.
Q5: The main GPU drops out during parallel work while the sub-GPU keeps going
On a single-PSU build this can be a capacity problem. Read the GPU and CPU draw with GPU-Z or HWiNFO64 and compare a rough total, plus an allowance for everything else, against the PSU’s rating. Those tools cannot report the PSU’s own load, so a wall meter or a PSU with power monitoring is what you need to see it properly. Running continuously near the rating raises temperature and fan speed and eats into margin, so two GPUs plus a CPU under sustained load want real headroom rather than a number that just fits on paper. Splitting the load across two supplies, as described above, is one way to get it.
Q6: For a new build in 2026, RTX 5060 Ti 16GB or RTX 4070 Super as the sub-GPU?
The RTX 5060 Ti 16GB is the sensible choice for a new build. VRAM capacity (16GB against 12GB) and power draw (180W against 220W) both favour it, and the 4070 Super is a generation behind with thin new stock, so in practice you would be comparing against used prices. On the other hand, for small and mid-sized models that fit in both, the 4070 Super has more memory bandwidth (504GB/s on its 192-bit bus against 448GB/s) and more CUDA cores (7,168 against 4,608), so there are workloads where it comes out ahead. Past 12GB, though, the 4070 Super starts spilling and loses that advantage, so if large models are the point, the 16GB card wins.
Q7: Is there a noticeable difference between Oculink x4 and PCIe x16 during generation?
For image generation (SDXL, Flux) where the model fits in VRAM and there is little host traffic, the effect of PCIe width on generation time tends to be small — the main work is internal to the GPU, so bus bandwidth rarely dominates. It shows up in model loading, and in workflows that push large preprocessor data across from the CPU, such as heavy ControlNet; LLM work loading a large model is affected the same way. Seconds of difference appear in total workflow time, less so per step. Note that this article does not compare x16 and x4 under matched conditions, so it cannot attribute the gap to bus width.
Summary
The most realistic way to use two GPUs with ComfyUI is port separation, which gives you two independent generation environments. Within the three custom nodes compared here and port separation itself, you get neither a transparent pooling of VRAM nor parallel execution of a single generation’s denoising across GPUs. For the latter there are other implementations ― the stock MultiGPU CFG Split and Raylight ― but none of them combines with port separation. When two cards differ noticeably in speed, throwing separate jobs at them beats forcing simultaneous processing.
Measured across images and video, what port separation earns is consistent: two jobs finish in roughly the time the slower card needs for one (1.53–1.57x for images, 1.67–1.68x for video). It is not that nothing slows down; it is that multiplier.
LLM inference is a different case, where a layer split across GPUs gives you a pseudo-pooled VRAM. The value of a second card varies enormously with what you intend to do, so decide that first. If the only goal is loading one large model, a single card with more VRAM beats investing in two.
References
- ComfyUI official repository: comfy/cli_args.py startup option definitions
- NVIDIA official: Ampere GPU Architecture Tuning Guide (Bfloat16 Tensor Core support)
- NVIDIA official: CUDA Programming Guide, “CUDA Environment Variables” (CUDA_VISIBLE_DEVICES / CUDA_DEVICE_ORDER)
- NVIDIA official: GeForce RTX 4090 specifications (NVLink / SLI-Ready: No)
- NVIDIA official: NVLink / NVSwitch technology page
- llama.cpp official: docs/multi-gpu.md (layer split and KV cache placement)
- Ollama official: Hardware support (GPU selection)
- ComfyUI-MultiGPU official repository
- ComfyUI-Distributed official repository
- Raylight official repository